RAG cost calculator
Work out the one-off and monthly cost of a retrieval-augmented (RAG) app, and what each question costs.
Free, runs in your browser, no sign-up. Updated 2026-10-25.
Result
RAG over 5,000 pages, 10,000 queries a month: $0 to embed once, then $83.36 a month ($0.0083 per query). Vector database not priced: enter your vendor's prices.
Vector database cost is $0 because no vendor price is filled in. Enter your vendor's price.
- Input tokens / query
- 2,630
- Cached tokens / query
- 720
- Vectors stored
- 7,316
- Storage
- 0.04 GB
| Part | Per month |
|---|---|
| LLM calls | $83.32 |
| Query embeddings | $0.03 |
| Re-embedding changed documents | $0.011 |
| Vector database | $0 (enter your vendor's price) |
| Total | $83.36 |
Assumptions
Every number the result depends on, and where it comes from. Change any value and the result updates.
| Assumption | Value | Source |
|---|---|---|
| Tokens per word | tokens | OceanLab planning assumption: common rule of thumb for English prose (see the token counter). Edit it for your language or for code.Reviewed 2026-10-25 |
| Words per page | words | OceanLab planning assumption: a dense single-spaced page. Edit it for your documents.Reviewed 2026-10-25 |
| Chunk overlap | % | OceanLab planning assumption: chunks usually share some text with their neighbour so context is not cut mid-thought; overlapping text is embedded twice.Reviewed 2026-10-25 |
| Share of the corpus re-embedded each month | % | OceanLab planning assumption: new and edited documents. Set 0 for a static corpus.Reviewed 2026-10-25 |
| Queries per month | queries | OceanLab planning assumption. Use your own traffic.Reviewed 2026-10-25 |
| Tokens in the user's question | tokens | OceanLab planning assumption: a one or two sentence question.Reviewed 2026-10-25 |
| Chunks retrieved per query (top-k) | chunks | OceanLab planning assumption: a common starting top-k. Tune it against answer quality.Reviewed 2026-10-25 |
| Tokens per chunk | tokens | OceanLab planning assumption: a common chunk size. Edit it to match your chunker.Reviewed 2026-10-25 |
| System prompt tokens (same on every query) | tokens | OceanLab planning assumption. Paste your prompt into the token counter for a better number.Reviewed 2026-10-25 |
| Answer tokens | tokens | OceanLab planning assumption: a few paragraphs.Reviewed 2026-10-25 |
| Share of system prompt served from cache | % | OceanLab planning assumption: the system prompt is identical on every call, so most calls can hit the provider's prompt cache. Set 0 if you do not use caching.Reviewed 2026-10-25 |
| Vector dimensions | dims | OceanLab planning assumption: depends on the embedding model and settings you choose. Used only for the storage estimate.Reviewed 2026-10-25 |
| Vector DB storage price per GB-month (USD) | USD | Enter your vendor's price. Not verified for any vendor, so it starts at 0. Enter your vector database's price.Reviewed 2026-10-25 |
| Vector DB price per 1M queries (USD) | USD | Enter your vendor's price. Not verified for any vendor, so it starts at 0. Enter your vector database's price.Reviewed 2026-10-25 |
| Vector DB fixed monthly fee (USD) | USD | Enter your vendor's price. Not verified for any vendor, so it starts at 0. Many hosted plans have a minimum or base fee.Reviewed 2026-10-25 |
Ask OceanLab about your RAG build
Opens an email to OceanLab with this result and a link to your inputs. Nothing is sent until you press send, and there is no sign-up.
How this is calculated
One-off: the corpus is turned into tokens (pages × words per page × tokens per word), chunk overlap is added, and it is embedded once at the model's price.
Monthly: re-embedding the share of documents that change, embedding each question, the vector database, and the LLM call. Each LLM call carries the system prompt (mostly from cache), the question and the retrieved chunks as input, plus the answer as output.
Vector database prices were not verified for any vendor, so they start at 0. Enter your vendor's storage, query and base fees. Storage assumes 4-byte floats plus 50% for the index and metadata.
Sources
- Google embedding pricing · checked 2026-10-25
- Voyage AI embedding pricing · checked 2026-10-25
- Anthropic API pricing · checked 2026-10-23
- OpenAI API pricing · checked 2026-10-23
- Google API pricing · checked 2026-10-23
- DeepSeek API pricing · checked 2026-10-23
- MiniMax API pricing · checked 2026-10-23
Questions about this tool
What makes up the cost of RAG?
Embedding the documents once, embedding each question, the vector database, and the LLM call, which carries the retrieved chunks as input. The LLM call is usually the largest part.
Why is the vector database at zero?
No vector database's prices were verified, so the defaults are 0. Enter your vendor's storage, query and base fees.
How do I lower the cost per query?
Retrieve fewer or smaller chunks, cache the system prompt, and try a cheaper model if answer quality holds up in testing.
Where do the prices come from?
Each price is read from the provider's official pricing page and shows the date it was checked. Prices that could not be verified are left out, or start at 0 for you to fill in.
Other free tools
OceanLab product builds like this
Products OceanLab designed and built. Each case study covers the screens, the scope and the rules it was built for.
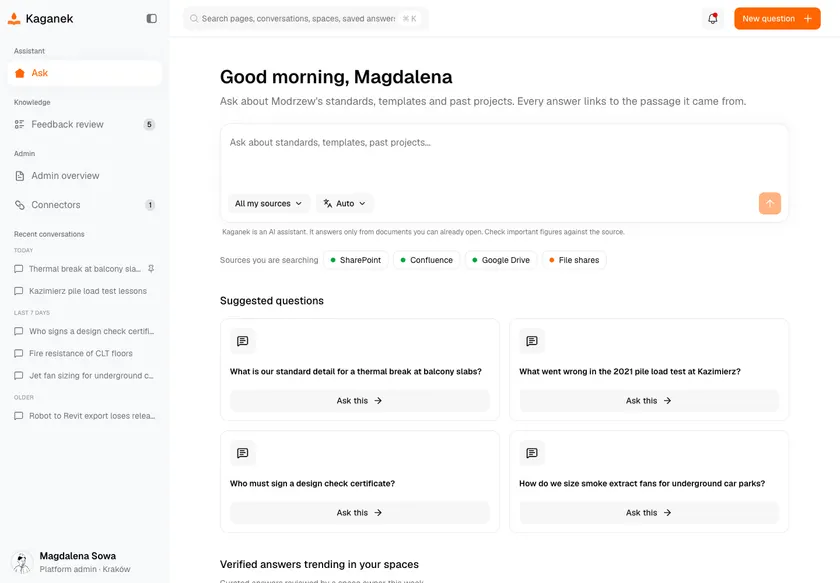
Kaganek - RAG Knowledge Assistant with Citations and Permissions Intact
Designed and built a clickable internal knowledge assistant for a Kraków consulting engineering firm: staff ask in Polish or English and get answers built only from the firm's own SharePoint, Confluence, Google Drive and file share documents, with every claim linked to its source passage and an honest "I don't know" when the sources are weak.
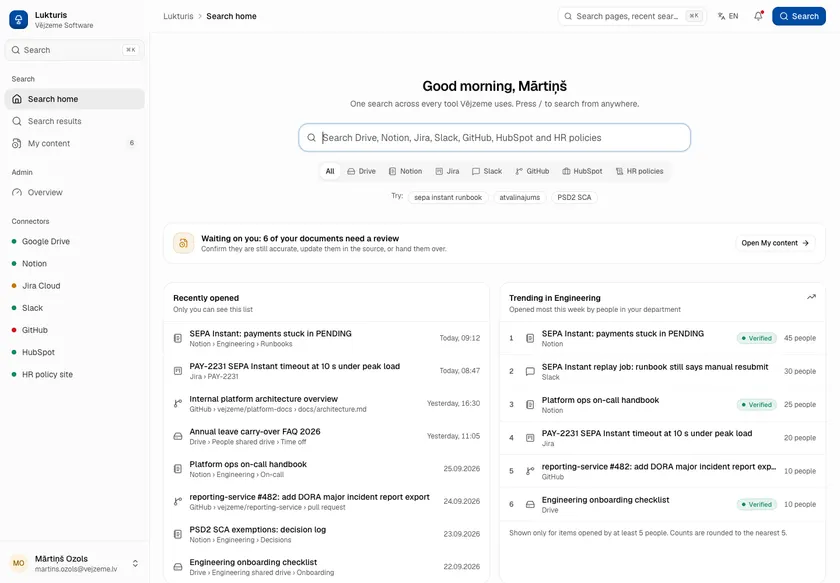
Lukturis - Permission-Aware Enterprise Search Across Seven Internal Tools
Designed and built a clickable enterprise search product for a 600-person Riga software company: one search box over Google Drive, Notion, Jira, Slack, GitHub, HubSpot and the HR policy site, with every result filtered by what the person can already open in the source tool, extractive answer cards that always link to the source, review nudges for content owners and an admin view of connector health and index freshness.
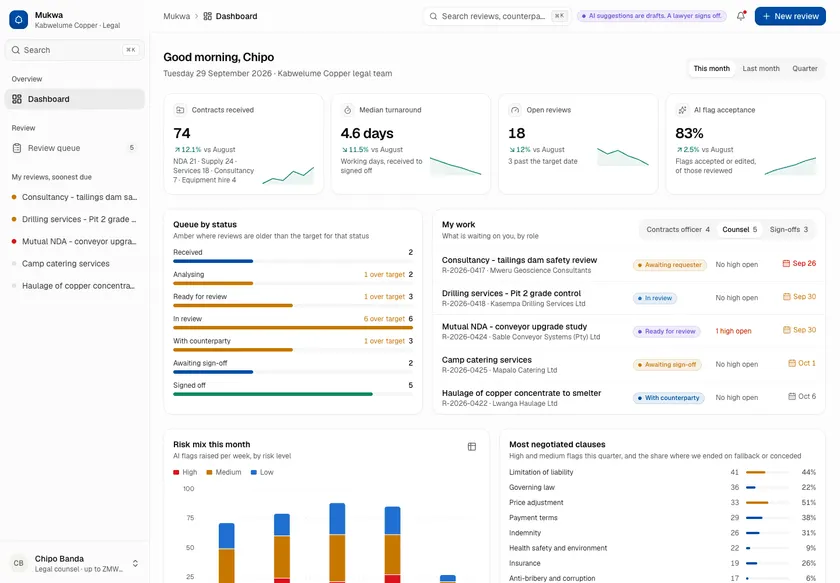
Mukwa - AI Contract Review Checked Against the Playbook and Signed Off by a Lawyer
Designed and built a clickable contract review tool for the in-house legal team of a Lusaka copper miner: the AI extracts each clause of a third-party contract, compares it with the company playbook, flags risks with a plain explanation and drafts redlines, while a lawyer decides every flag and only a lawyer with the right authority can sign off.
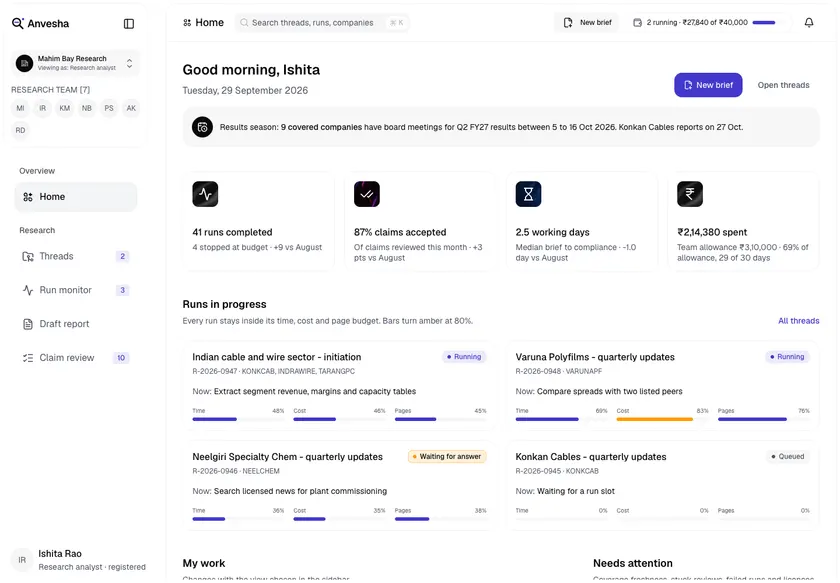
Anvesha - Deep-Research Agent for Cited Equity Research
Designed and built a clickable deep-research agent for a SEBI-registered Mumbai research boutique: analysts brief the agent, watch each run stay inside its time, cost and page budget, and get a draft report in which every factual sentence links to a quoted source passage they must accept before it can leave the team.
